We let an AI decide what a government grant is about
How SpendQuery uses a narrow AI judge to tag federal awards by topic, while every dollar figure still comes straight from the records.
We let an AI decide what a government grant is about. It never touches the dollar figures.
SpendQuery lets anyone ask plain-English questions about US federal spending. Topics such as “broadband”, “COVID” or “semiconductors” are some of our most-used features, but tagging awards by keywords is noisy.
Our “broadband” topic included highway grants to “reconnect communities”, an interstate widening project, and rental-aid grants that list internet as just one allowed use.
So we added Jev from TypeSafe. It doesn’t write text. It answers narrow questions with a probability: Is this award mainly about broadband, or does it only mention it? What does it pay for? The picture shows the whole pipeline and one real example.
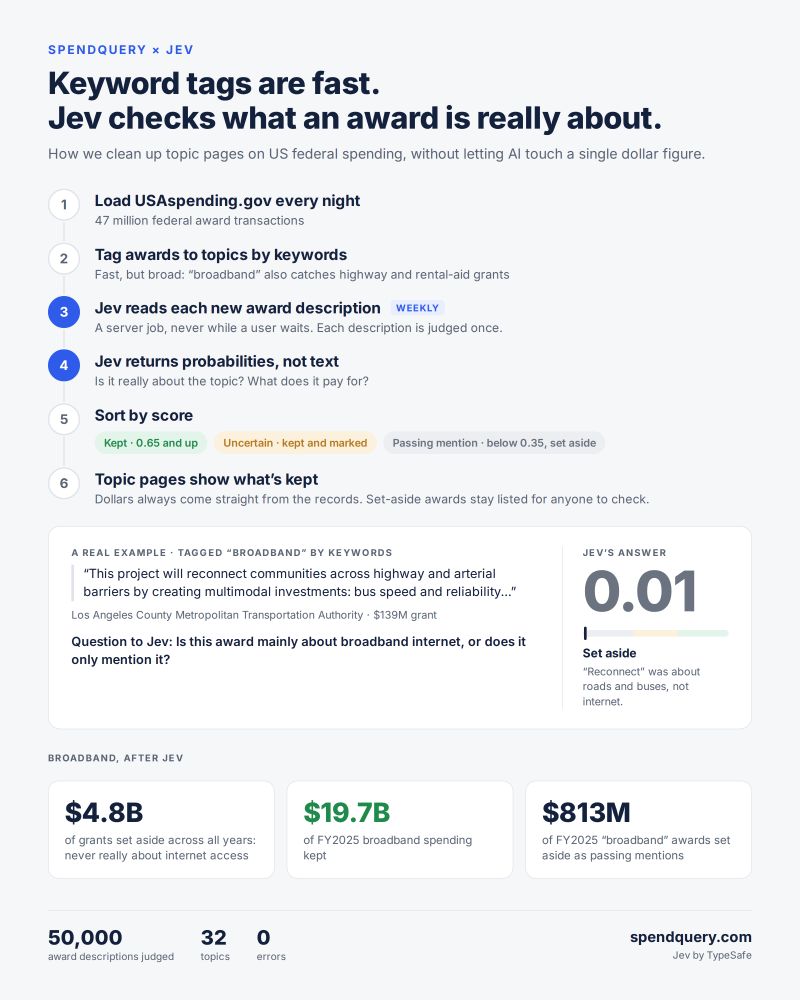
Three rules we kept
- It runs as a weekly server job, never while a user is waiting, and each description is judged once.
- Unsure scores are kept and marked, not quietly dropped.
- Every dollar on the page still comes straight from the records.
How it held up
We tested it first on 55 awards we labelled by hand, and it agreed with us 93% of the time. Since then it has judged 50,000 award descriptions across 32 topics, with zero errors.
The biggest lesson: how you word the question matters as much as the model. Our first COVID question removed contracts paid for from pandemic relief funds. One sentence fixed it, and the re-check took three minutes.
Next: using Jev to check that each answer covers every part of the question you asked.